

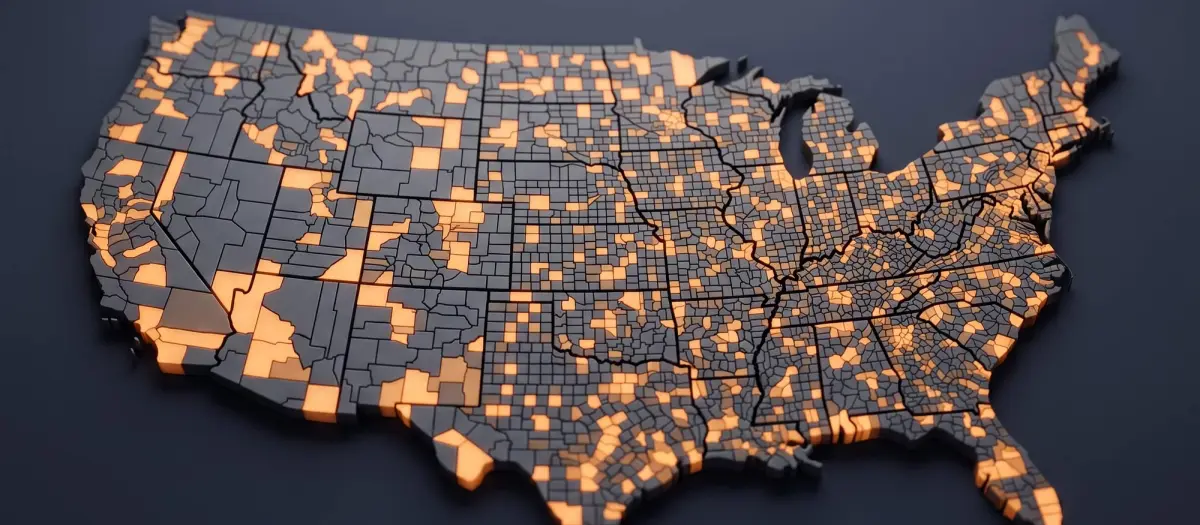
A geo test compares what happened in the markets that got the spend with a matched set of markets that did not.
Ad platforms report conversions, but they can't tell you which of those customers would have bought anyway. When reported ROAS looks healthy and the P&L doesn't move with it, finance starts asking what the spend actually caused. Answering that takes an incrementality test, and many teams assume that means hiding ads from a random group of customers, which they can't or won't do.
You can measure incrementality without a user-level holdout group by changing what you compare against. Geo tests withhold or increase spend by region. Synthetic control and Bayesian time-series models build a counterfactual from data you already have. Marketing mix modeling estimates lift from spend variation over time, and it is most reliable when calibrated with experiments.
A clarification: almost every approach below still uses a control of some kind. What changes is the unit: instead of hiding ads from a random slice of customers, you compare regions, time windows, or a modeled baseline.
What is incrementality, and how is it different from attribution?
Incrementality is the share of an outcome that would not have happened without the marketing. It is measured as the difference between what actually happened and a counterfactual: what would have happened if the spend had not run.
Attribution answers a different question. It divides credit for conversions that already happened among the touchpoints before them, so it cannot tell you whether a customer would have bought anyway. We cover how to match attribution models to the decisions they suit in Stop Debating Attribution Models. Use Them All. This piece covers the validation layer that sits above them.
A simple illustration shows why the gap matters. Say a retargeting campaign reports 1,000 conversions on $50,000 of spend, a $50 CAC. A test then shows that 700 of those buyers would have purchased without the ads. The campaign caused 300 conversions, so its incremental CAC is about $167. The platform report did not change. The real cost per customer more than tripled.
Most incrementality work reports some version of these numbers:
- Incremental lift: the percentage increase in the outcome caused by the marketing, relative to the counterfactual.
- Incremental CAC (iCAC): spend divided by incremental customers or conversions.
- Incremental ROAS (iROAS): incremental revenue divided by spend. Build it on contribution margin where you can.
Why measure incrementality without a holdout group?
A user-level holdout, where a random group of people is prevented from seeing your ads, is the cleanest design available. It is also unavailable or impractical in a lot of real situations:
- The channel cannot be split by user. Linear TV, out-of-home, podcasts, and radio rarely let you withhold ads from a random set of individuals.
- Conversions happen where tracking cannot follow. Cookies get deleted and people switch devices. Offline purchases rarely connect back to an ad exposure at all. Google's data science team cites these problems as a core reason for designing experiments around geography.
- The business will not go dark on customers. Withholding ads from 10% of your audience during peak season is a hard sell, even when it is the right test.
- You need a read on something that already happened. A channel launched last quarter without a test design still needs an answer.
What are the main ways to measure incrementality without a holdout group?
There are seven methods worth knowing. They differ mostly in the data they need and the question they can answer.
1. Geo tests and matched-market tests
A geo test assigns regions, not people, to treatment and control. You pause or raise spend in the treatment regions, then compare their outcomes with matched control regions over the same period. In the US, tests often use Nielsen media markets as the unit. Google's published method randomizes regions in groups of similar size so treatment and control stay balanced.
Google describes a pretest period of typically 4 to 8 weeks and a test period of typically 3 to 5 weeks, with an optional cool-down to capture delayed conversions. Meta's open-source GeoLift package adds a useful rule of thumb: the test period should contain at least one full purchase cycle.
Geo tests work best when the channel can be targeted by region and each region produces enough conversions to read. They also need enough regions: the authors of Google's method say they prefer to use it on experiments with 30 or more geos, which is easier in the US than in smaller countries. The main risks are spillover (people who live in one market and buy in another, or national campaigns that reach every region) and local events, such as a regional promotion that lands in only one group. Geo testing is one of the methods Exactius operators run when a user-level split is off the table, and the design work matters more than the readout, above all knowing in advance what size of lift the test can detect.
2. Synthetic control
Synthetic control builds a weighted blend of untreated units that tracks the treated unit closely before the intervention. After the intervention, the gap between the real unit and its synthetic twin is the estimated effect. Its best-known application, by Abadie, Diamond, and Hainmueller, estimated the effect of California's tobacco control program. GeoLift uses an augmented version for marketing tests.
It suits situations with one or a handful of treated markets, or a launch that was not randomized. It needs a long, stable pre-period and a pool of candidate control units that were not exposed. If the synthetic version does not track the real one closely before the launch, do not trust what it says afterward.
3. Causal impact and Bayesian structural time series
Causal impact models predict what a metric would have done without an intervention, using related time series that the intervention did not touch. The approach comes from a 2015 paper by Brodersen and colleagues at Google in the Annals of Applied Statistics, and Google maintains it as the open-source CausalImpact R package. The output is an estimated effect with a credible interval, which makes uncertainty visible.
The package documentation is explicit about two assumptions: the control series were not affected by the intervention, and the relationship between controls and the outcome stays stable through the test. Both are easy to break in marketing. If you are measuring a TV launch, branded search volume is a poor control, because TV drives branded search. The method is a common choice for a retroactive read on a launch nobody designed a test for.
4. Time-based on/off and switchback tests
A time-based test alternates spend between on and off periods, such as one week running and one week paused, and compares the outcome across windows. A switchback test randomizes which time blocks get the treatment, which protects the result from a single good or bad week.
These tests fit channels where the effect shows up fast and fades fast, like paid search and promotional offers. They break down when effects carry over: brand media keeps working after it stops, so a paused week still benefits from the week before. Run several cycles, randomize the order, and control for seasonality. DoorDash's data science team has published an adapted switchback design it used to measure the incrementality of app store search ads, a channel that offered neither user-level randomization nor precise geo-targeting.
5. Marketing mix modeling
Marketing mix modeling (MMM) uses regression on aggregate spend and outcome data to estimate each channel's contribution, including offline channels and diminishing returns. It needs no user-level data at all. Meta's Robyn documentation states that robust results need a minimum of two years of weekly data, and that the number of rows should be roughly 7 to 10 times the number of variables.
Robyn and Google's Meridian, made available to everyone in January 2025, are both open source, and both are built to take experiment results as calibration inputs.
The weakness of MMM is correlated spend. If every channel scales up together in Q4, the model struggles to separate them. An uncalibrated MMM is a hypothesis about incrementality. A geo test is how you check it.
6. Platform conversion lift studies
Meta and Google both offer conversion lift studies run inside their platforms. Google offers two types: user-based and geography-based. The user-based version does use a randomized holdout, but the platform builds and manages it, so you do not have to. Google notes that the budget is set during setup based on historical conversion data, and that geography-based studies tend to need more budget than user-based ones.
These studies are the fastest way to check whether spend on one platform is incremental. To be precise, the user-based version is a user-level holdout. It belongs on this list because the platform runs it, so you never have to build or manage one yourself. Google flags two practical limits: user-based studies rely mostly on opt-in traffic, so results can be affected by measurement gaps, and geography-based studies are only available through your Google account representative. The platform also designs the test and counts only the conversions it can observe, so check the results against your own backend data.
7. Ghost ads and PSA tests
In a public service announcement (PSA) test, the control group sees an unrelated charity ad in place of yours, and you pay for every control impression. With ghost ads, the platform records when it would have shown your ad to a control user without showing it, so the control costs you no media.
The method was set out by Johnson, Lewis, and Nubbemeyer in the Journal of Marketing Research in 2017. They report that advertisers can measure lift as precisely as with PSA or intent-to-treat tests while spending at least an order of magnitude less. The catch is availability. Ghost ads depend on the ad platform's infrastructure, so you can only use them where a platform offers them. Like platform lift studies, ghost ads still rely on a user-level control. They are on this list because the platform runs that control, not you.
Which incrementality method should you use?
Start from the decision, then pick the method that can answer it with the data and time you have:
- Geo test: a forward-looking read on one channel or spend change, where regional targeting is possible.
- Synthetic control or causal impact: a read on a launch that was not randomized or has already happened.
- On/off or switchback: fast-response channels with little carryover.
- MMM: allocation across the full mix, including offline, once you have about two years of weekly data.
- Platform lift study or ghost ads: a quick check on one platform, where the platform supports it.
Mature programs combine them: an MMM for the portfolio view, with geo tests and lift studies checking the largest channels and feeding results back into the model.
How much data, spend, and time does an incrementality test need?
There is no universal minimum, because what matters is the size of the lift you are trying to detect relative to the normal noise in your data. A test that cannot detect a 5% lift will likely come back inconclusive if the true lift is 3%, no matter how well it was run.
Run a power analysis before you launch. It uses historical data to estimate the smallest effect a given design can detect. GeoLift includes this step, and it is worth doing for any method. If the detectable effect is larger than the lift you realistically expect, change the design. Add markets or extend the test, or make the spend change larger.
An illustration, with made-up numbers: say your test markets together average 2,000 orders a week, and those orders normally swing about 10% from one week to the next. You expect the channel you are testing to drive a 3% to 5% lift. A power analysis on your history shows a two-week test across those markets can only reliably detect lifts of 8% or more. Run it as planned and the most likely outcome is an inconclusive result that tells you nothing. Change the design until the detectable lift falls below the lift you expect, and only then commit the budget.
What are the most common incrementality testing mistakes?
- Stopping early because the result looks good. Checking results daily and stopping at the first significant reading inflates false positives. Set the duration in advance and hold to it.
- Ignoring carryover. If you pause brand media for two weeks and read only those two weeks, you miss the delayed effect. Include a cool-down period in the analysis.
- Contaminated controls. A national campaign or a regional promotion can distort control regions. Log every other change during the test window.
- Reading inconclusive as zero. A result that is not statistically significant means the test could not detect an effect of that size. It does not prove the channel does nothing.
- Measuring platform conversions instead of business outcomes. Read the test on orders in your own backend and on contribution margin. Strong ROAS often fails to show up in the P&L for exactly this reason.
- Testing once and assuming the answer holds. Incrementality changes as spend grows and audiences saturate. A result from 18 months ago at half the budget describes a different channel.
How do you turn incrementality results into budget decisions?
First, convert lift into incremental CAC and compare it with lifetime value on a contribution-margin basis. Our guide to ecommerce LTV:CAC covers how to build both sides of that ratio so the comparison holds.
Second, match the test to the decision. A go-dark test tells you the average contribution of a channel at current spend. A heavy-up test tells you what the next dollar does. Budget decisions happen at the margin, so a channel that looks strong on average can still be past the point where more spend pays back.
Third, read the interval, not the point estimate. If the plausible range for incremental CAC runs from profitable to unprofitable, hold the budget where it is and re-test with more power.
Fourth, carry the result into daily reporting. Many teams calculate the ratio of incremental conversions to platform-reported conversions and apply it to platform numbers until the next test. If a test finds that 40% of reported conversions were incremental, a reported $50 CAC becomes a working estimate of $125. Treat that number as an estimate at the spend level you tested. Returns usually diminish as spend rises and audiences saturate, so the next dollar is often less incremental than the average one. Re-test before you scale a channel on the strength of it, and feed the same results into your MMM as calibration.
Finally, put tests on a calendar. Rank channels by spend and by how uncertain their incrementality is, and test the top of that list first.
Sources
- Google, Unofficial Google Data Science blog: estimating causal effects using geo experiments (2016)
- Meta, GeoLift walkthrough (GitHub)
- Abadie, Diamond, and Hainmueller, synthetic control and California's tobacco control program (NBER working paper 12831)
- Brodersen et al., Inferring causal impact using Bayesian structural time-series models, Annals of Applied Statistics (2015)
- CausalImpact R package documentation
- Meta, Robyn analyst's guide to marketing mix modeling
- Google, announcement of Meridian's availability to everyone (2025)
- Google Ads Help, conversion lift studies
- Johnson, Lewis, and Nubbemeyer, Ghost Ads: Improving the Economics of Measuring Online Ad Effectiveness (SSRN)
- DoorDash, adapted switchback testing to quantify incrementality for app marketplace search ads (2022)
If you want a second set of eyes on a test design before you commit spend to it, book a call and an Exactius operator will walk through what your data can and cannot detect.
Exactius is a full-funnel growth agency accountable for its clients' P&L. Its AI-enabled senior operators provide performance marketing, strategy, creative, and whole-business analytics and data science, engaged one function at a time or as a full team. It serves consumer and B2B companies where paid marketing is a main growth lever, through two practices: one for companies from $5M to $100M and one for companies from $100M to $1B.
David Manela
David Manela is the founder of Exactius and creator of the Growth Operating System — a framework for deploying capital-efficient, compounding growth inside scaling companies.
FAQ
Frequently asked
What is incrementality in marketing?
Incrementality is the share of conversions, revenue, or customers that would not have happened without a specific marketing activity. It is measured by comparing actual results with a counterfactual, an estimate of what would have happened if the spend had not run. Attribution divides credit among touchpoints for conversions that already happened. Incrementality asks whether those conversions were caused by the marketing at all.
Can you measure incrementality without a control group?
You always need a comparison of some kind, because incrementality is defined against a counterfactual. What you can avoid is a user-level holdout. Geo tests compare treated regions with control regions. Synthetic control and causal impact models build a modeled baseline from untreated data. Time-based tests compare on and off periods. Marketing mix modeling estimates the counterfactual from spend variation over time.
How long should a geo incrementality test run?
Long enough to cover at least one full purchase cycle, which is the rule of thumb in Meta's GeoLift documentation. Google's published geo experiment method describes a pretest period of typically 4 to 8 weeks and a test period of typically 3 to 5 weeks, with an optional cool-down to capture delayed conversions. Run a power analysis first to confirm the planned duration can detect the lift you expect.
What is the difference between incrementality testing and marketing mix modeling?
An incrementality test is an experiment that measures the causal effect of one change, such as pausing a channel in selected regions. Marketing mix modeling is a statistical model built on two or more years of aggregate data that estimates every channel's contribution at once. Tests are more precise for a single question. MMM covers the full mix. The two work best together, with test results used to calibrate the model.
Are Meta and Google conversion lift studies reliable?
They are randomized experiments, so the design is sound for what they measure: the incremental effect of spend on that one platform, using the conversions the platform can observe. Their limits are scope and independence. They cannot compare platforms against each other, and the platform selling the media also runs the test. Treat them as one input and check the results against orders and revenue in your own systems.
What is incremental CAC?
Incremental CAC is marketing spend divided by the number of customers that spend actually caused, as measured by an incrementality test or calibrated model. It is usually higher than the CAC reported by ad platforms, because platforms count conversions that would have happened anyway. Comparing incremental CAC with contribution-margin LTV shows whether a channel is creating profit at its current level of spend.
How often should you run incrementality tests?
Re-test whenever spend on a channel changes materially, and on a regular calendar for the largest channels. Incrementality shifts as budgets grow and audiences saturate, so a result from a year ago at a lower spend level may no longer hold. Many teams rank channels by spend and by how uncertain their incrementality is, then test the top of that list each quarter.
Related Reading
Keep going
Ready to fix the system?
Your growth system is either compounding or degrading.
Book a diagnostic call. We'll identify where your growth system is breaking and what it's costing you.